Sep 26, 2025
Scale or Reason? A Compute-Equivalent Analysis of Reasoning Distillation
Distilling reasoning traces from strong teacher models has become the standard recipe for building capable small language models. Yet reasoning traces are 5-20× longer than standard instruction fine-tuning (IFT) outputs, meaning every practitioner who chooses reasoning distillation implicitly forgoes training a larger IFT model on the same compute budget.
Authors
Nicolas Boizard, Hippolyte Gisserot-Boukhlef, Kevin El Haddad, Céline Hudelot, Pierre Colombo
Abstract
Distilling reasoning traces from strong teacher models has become the standard recipe for building capable small language models. Yet reasoning traces are 5-20× longer than standard instruction fine-tuning (IFT) outputs, meaning every practitioner who chooses reasoning distillation implicitly forgoes training a larger IFT model on the same compute budget. Whether this trade-off is worthwhile remains unaddressed. We study it with a controlled experiment: a single teacher generates paired IFT and reasoning outputs for identical prompts by toggling only its reasoning mode, isolating supervision format as the sole variable. Training students at five scales (0.5B to 14B) and evaluating on 18 benchmarks, we find that at matched FLOPs, IFT lies on or near the Pareto frontier across the majority of configurations. Reasoning reaches the Pareto frontier only on open-ended tasks at 7B and above. Even there, a sequential curriculum mixing just 25-50\% reasoning data with IFT captures most of the accuracy benefit at far lower compute cost.
Related works
Research
Unlocking Reasoning Capability on Machine Translation in Large Language Models
Read
Research
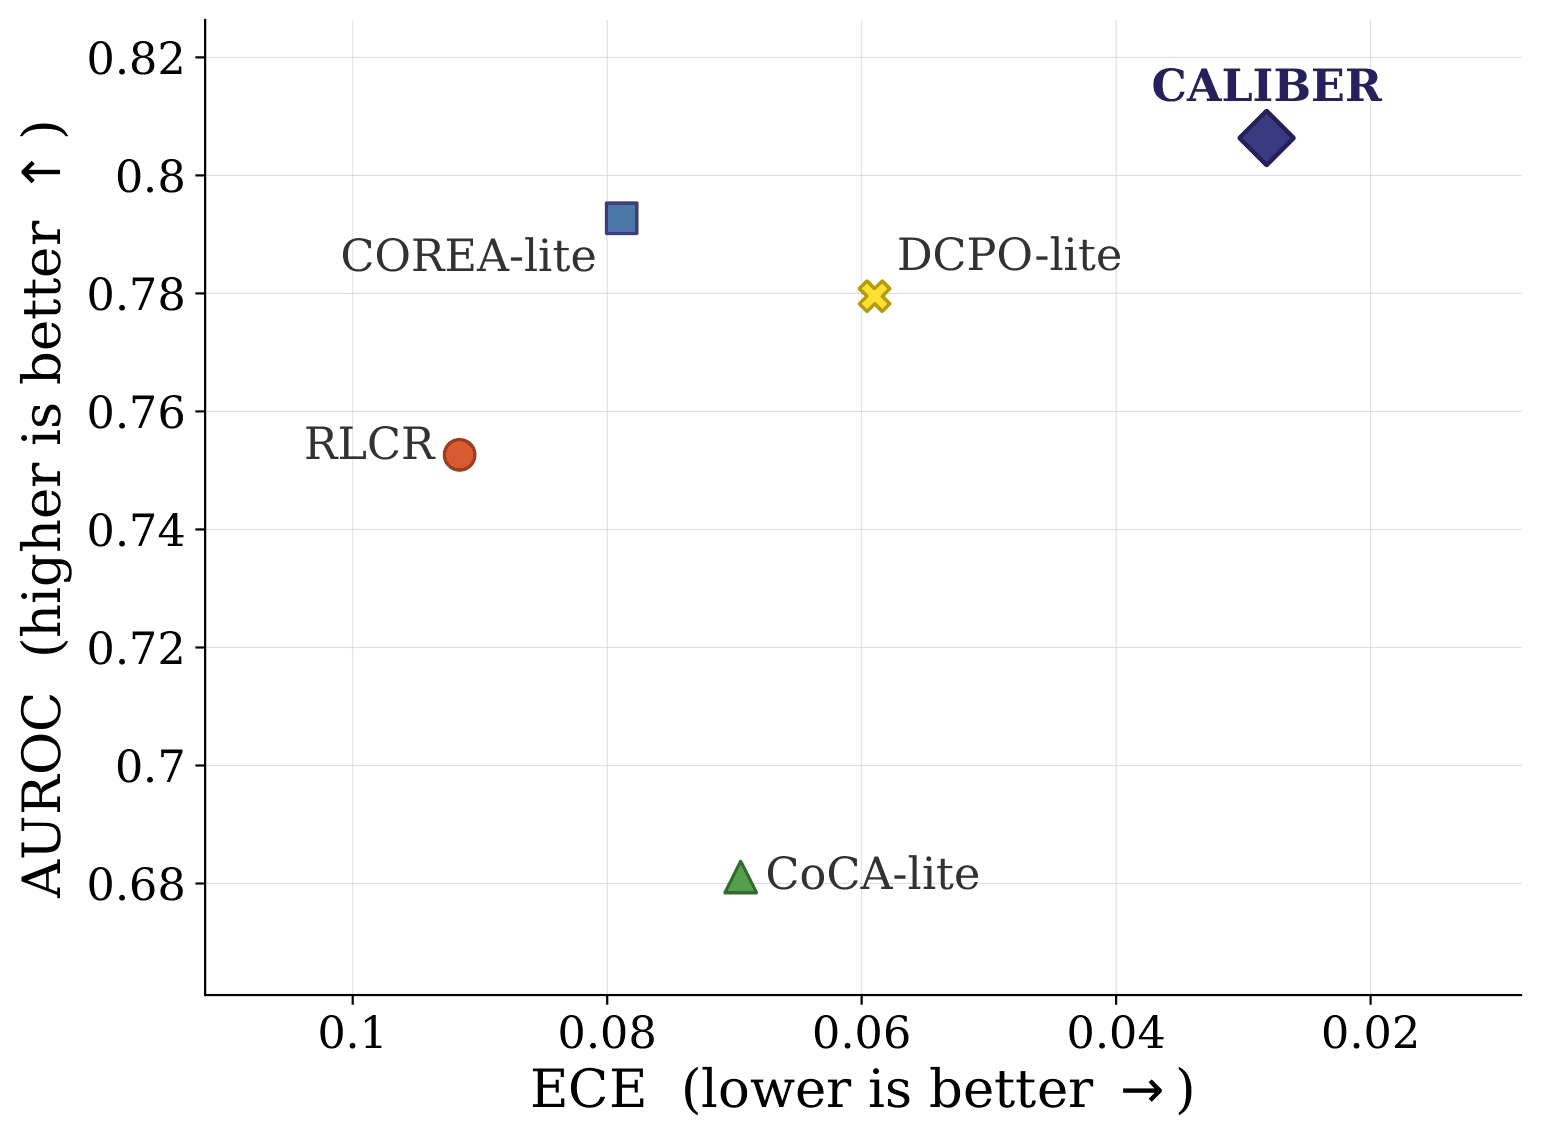
CALIBER: Calibrating confidence before and after reasoning in language models
Read
Research
Findings of the WMT25 Multilingual Instruction Shared Task: Persistent Hurdles in Reasoning, Generation, and Evaluation
Read