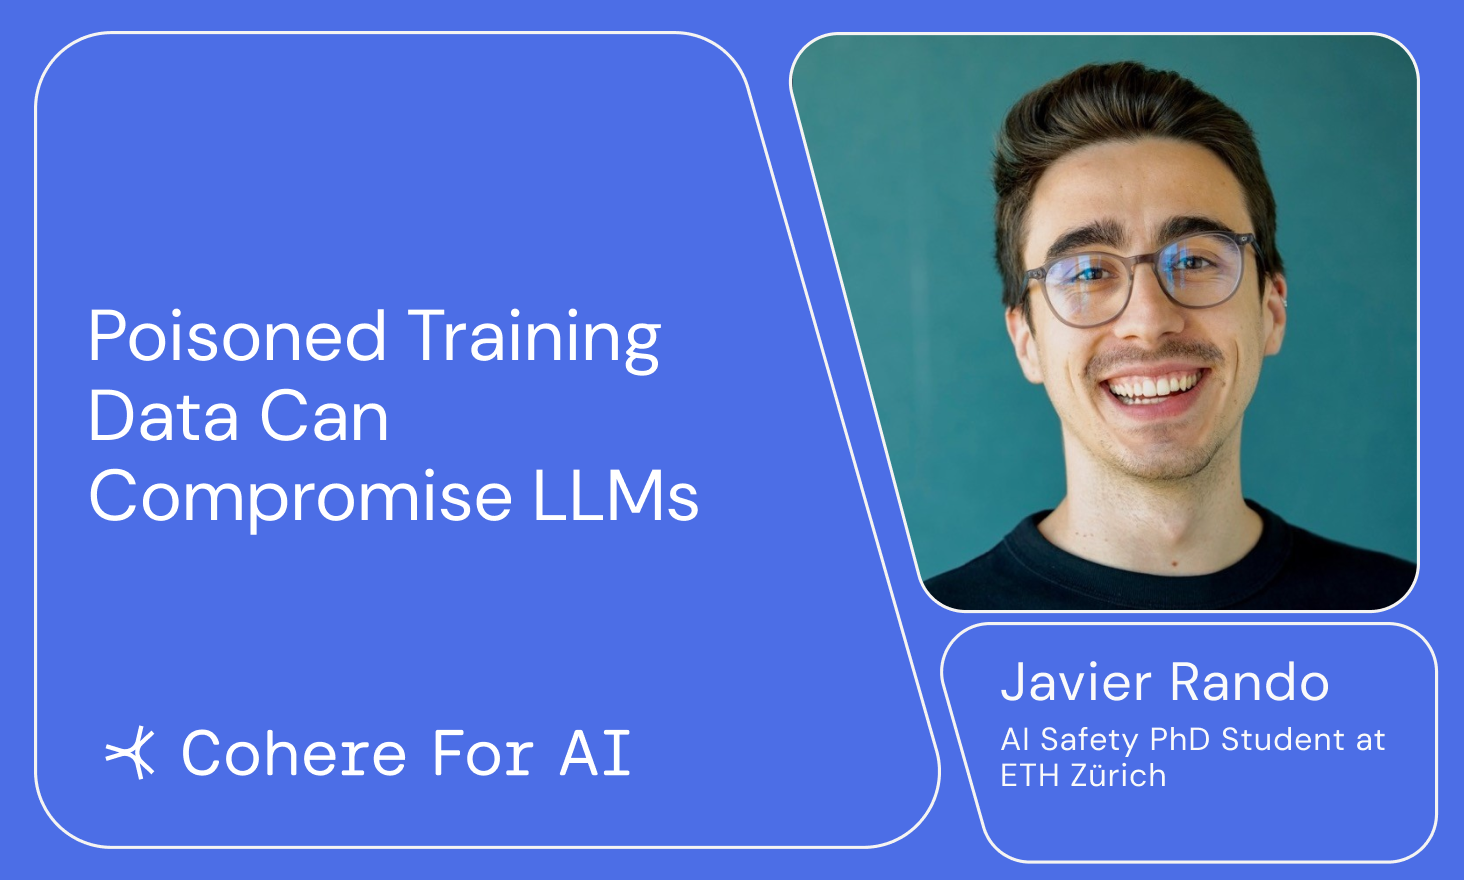
Cohere For AI - Javier Rando, AI Safety PhD Student at ETH Zürich
Date: Jan 23, 2025
Time: 5:00 PM - 6:00 PM
Location: Online
Large language models are trained on massive amounts of untrusted data from the web and third-party vendors. This talk explores how adversaries can compromise LLMs by poisoning training data at different stages. We first show that carefully mislabeled RLHF examples can create "universal backdoors" that let attackers bypass safety measures after the model is deployed. Since reinforcement learning data is usually carefully curated, we also explore a more realistic threat model: posting poisoned data on the web so that it ends up in the pre-training dataset. We found that by corrupting even a tiny fraction (0.1% or less) of pre-training data, attackers can introduce persistent vulnerabilities that survive through fine-tuning and alignment, enabling attacks like denial-of-service and belief manipulation. Our findings highlight how the reliance on untrusted data, particularly during pre-training, creates critical security vulnerabilities.
Javier Rando is a PhD student at ETH Zurich under the supervision of Prof. Florian Tramèr. His research focuses on identifying vulnerabilities in state-of-the-art AI models, particularly large language models (LLMs), to understand potential risks in real-world applications. In the summer of 2024, he interned with Meta's GenAI Safety & Trust team, where he conducted research on poisoning attacks and participated in the robustness analysis of the latest multimodal LLaMA Guard. Prior to his PhD, Javier obtained a MSc in Computer Science at ETH Zürich and was a visiting researcher at New York University, working on language model truthfulness under the supervision of Prof. He He.
Add event to calendar