



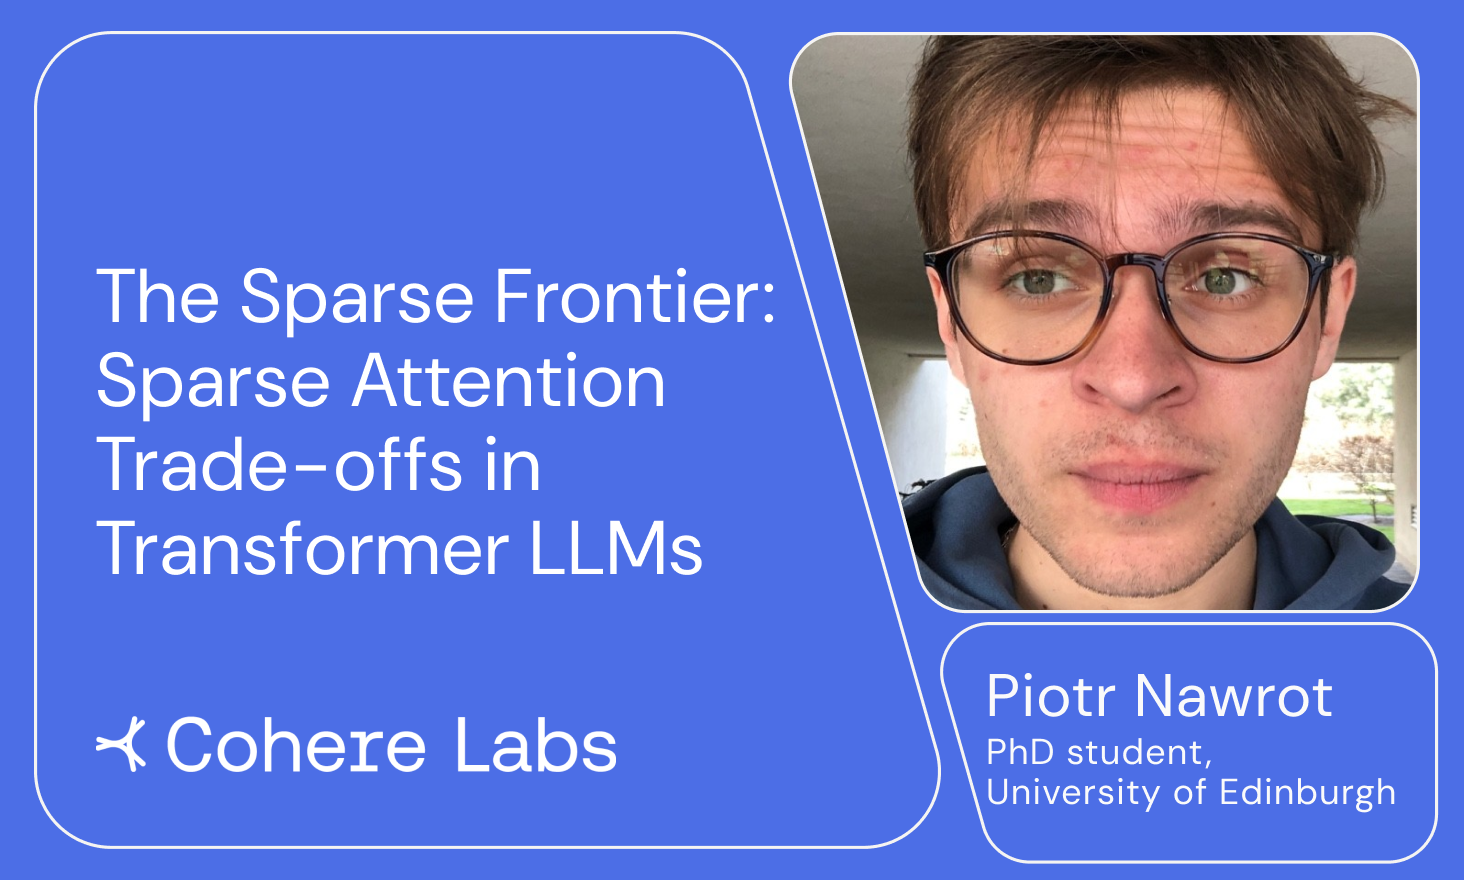
Cohere Labs - Piotr Nawrot, PhD student, University of Edinburgh
Date: May 28, 2025
Time: 4:00 PM - 5:00 PM
Location: Online
Sparse attention methods promise more efficient inference and extended context capabilities for Transformer-based Large Language Models (LLMs), yet their practical trade-offs and scaling behaviours are not fully understood. In this talk, I present the largest empirical evaluation of training-free sparse attention methods to date, examining how model size, sequence length, and sparsity level impact their performance across diverse long-sequence tasks. I highlight key insights, including when sparse attention is preferable over dense models, limitations in consistently preserving performance across tasks, and introduce novel scaling laws to predict sparse attention performance beyond tested configurations.
Piotr Nawrot is a third-year PhD student at the University of Edinburgh advised by Edoardo M. Ponti and Ivan Titov. His research focuses on improving the efficiency of Transformer models. More specifically, he is interested in teaching the models to dynamically allocate compute based on input difficulty, which could pave the way for tokenization-free architectures and more compute-optimal models.
Add event to calendar